Byteification bridges gap between subword and byte-level AI models
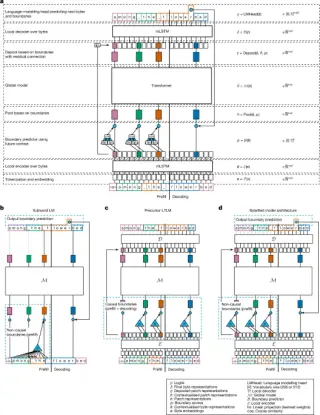
Researchers from the Allen Institute for AI (Ai2) have published a method called 'byteification' in Nature, which converts existing subword-based large language models (LLMs) into byte-level models with minimal additional training. This approach addresses the historical performance lag of byte-level models, which process text at the character level rather than as word fragments. By retrofitting models like Olmo, Qwen, and Llama, the new byteified versions achieve performance comparable to their subword counterparts while excelling in character-level reasoning tasks. The method requires less than 1% of a typical pre-training budget, offering a cost-effective path to developing models that handle scientific data, code, and diverse languages more accurately without the biases inherent in subword tokenization.